GPU Cloud
Elastic GPU capacity optimized for real AI workloads — inference, fine-tuning, and batch compute.
What This Product Does
High-Throughput Compute
Tuned for production AI workloads—including private inference, fine-tuning, and high-throughput batch compute.
Predictable Capacity & Sovereignty
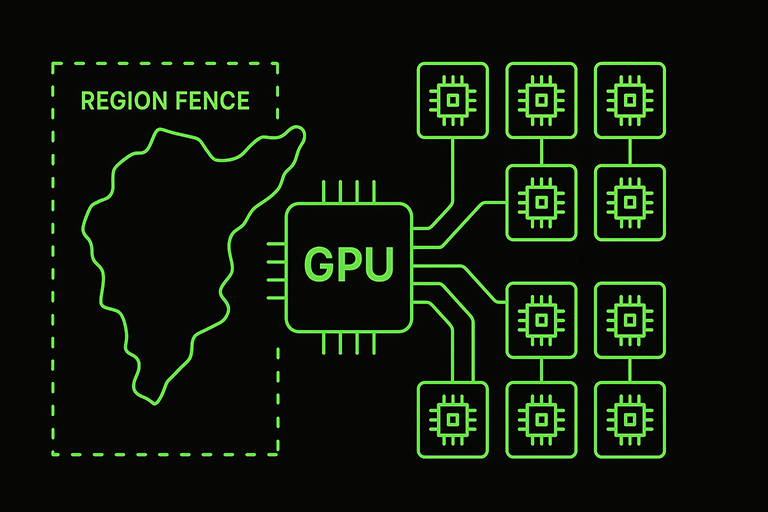
Region-aligned GPU pools with workload-level deployment metadata, giving enterprises clear visibility into where compute runs and how capacity is allocated.
Private GPU Execution
Dedicated and low-contention GPU options with tenant-aware isolation, separate operational metadata, and transparent deployment controls.
GPU Cloud Features
A GPU layer designed for region-aligned, residency-sensitive enterprise AI workloads.
Region-Pinned GPU Scheduling
GPU workloads can be scheduled according to configured regional and residency requirements across defined infrastructure environments.
Infrastructure Execution Controls
Configure workload routing, storage domains, and regional placement at the infrastructure layer to maintain defined tenant and deployment boundaries.
Dedicated & Shared GPU Pools
Choose between dedicated GPU clusters for your most sensitive workloads or optimized shared pools for cost-efficient training and inference.
Burst Capacity Without Losing Sovereignty
Access additional GPU capacity while maintaining configured regional and residency requirements across participating infrastructure environments.
Observability & Cost Telemetry Built-In
See which workloads consumed which GPUs, in which region, and at what cost. Export metrics to your existing observability stack.
Ready for Enclave-Protected Execution
GPU Cloud supports Attababy’s enclave-capable compute environments for high-sensitivity workloads requiring additional execution isolation.
GPU Cloud, Built for Sovereignty From the Ground Up
Attababy’s GPU Cloud is a region-segmented, residency-aware GPU infrastructure layer designed for enterprise AI workloads where compute location, data locality, deployment control, and operational visibility matter alongside performance.
Attababy provides infrastructure controls designed around regional deployment, tenant separation, and workload visibility:
Workloads can be aligned with configured regional deployment domains
GPU deployments can inherit configured regional and tenant requirements
Operational logging can be aligned with configured infrastructure environments.
This foundation supports high-speed inference, fine-tuning, batch processing, vector workloads, and agent systems while maintaining greater control over deployment location and infrastructure boundaries.
Whether you’re deploying LLaMA, Mistral, Qwen, custom proprietary models, high-throughput batch inference, or GPU-heavy vector indexing jobs—Attababy provides region-aligned deployment options and infrastructure-level operational visibility for private and open-weight models, batch inference, and GPU-intensive workloads.
Designed for Real Production AI, Not Lab Benchmarks
Attababy’s GPU layer was engineered to support long-running, load-sensitive, latency-aware AI systems, including:
Complex RAG workloads
Agent fleets with adaptive routing
High-volume token generation pipelines
Tensor indexing for multimodal search
Fine-tuning jobs requiring defined regional deployment controls
You get the performance of a hyperscaler GPU cluster—but without losing visibility, control, or sovereignty.
Full-Tenant Isolation, All the Way Down
Attababy supports dedicated and shared GPU environments designed around enterprise tenant separation and infrastructure visibility
Available capabilities include:
Dedicated or tenant-aware GPU capacity
Separate operational metadata and logging pathways
Encryption in transit and at rest
Configurable zero-persistence execution options
Infrastructure metadata compatible with regulated enterprise audit environment.
These controls allow organizations to choose the level of infrastructure separation appropriate for sensitive, regulated, and mission-critical AI workloads.
Why Attababy GPU Cloud
Most GPU infrastructure was designed around general-purpose compute. Attababy is designed around the additional regional, isolation, and operational requirements of sensitive enterprise AI.
- Region-aligned GPU deployment for residency-sensitive workloads
- Configurable zero-persistence options for sensitive inference workloads
- Operational metadata designed for enterprise audit workflows in regulated environments
GPU Cloud Use Cases
Real workloads—not demos. Here are the kinds of sovereign AI systems teams run on Attababy’s GPU Cloud.
Region-Fenced Inference for Regulated Workloads
Run inference within configured regional infrastructure environments for workloads subject to residency and jurisdictional requirements:
Healthcare PHI (HIPAA, HITRUST)
Financial data (SOX, PCI, PSD2)
EU-restricted data (GDPR, EU AI Act)
APAC & LATAM sovereignty rules
Regional deployment requirements can be configured at the infrastructure level.
Zero-Persistence AI Model Execution
For sensitive workloads requiring minimal runtime persistence, Attababy supports configurable zero-persistence execution within enclave-capable compute environments.
Persistence behavior can be configured according to workload and enterprise requirements while preserving non-content operational visibility.
High-Throughput Vector Indexing & RAG Preprocessing
GPU-accelerated workloads for:
Embedding generation
Multimodal vector construction
Batch document ingestion
Large-scale text, image, and audio preprocessing
Index rebuilding jobs
These workloads can operate within the same region-aligned and tenant-aware infrastructure used by Attababy’s vector and retrieval services.
Agent Fleet Acceleration with Infrastructure Isolation
Organizations operating large fleets of AI agents can leverage Attababy’s GPU Cloud for high-performance routing, planning, and generation workloads while maintaining strict region and tenant infrastructure isolation.
Infrastructure-level controls support:
Region-aligned execution
Tenant-specific execution environments
Operational metadata visibility
Configurable network boundaries